The chapter so far has studied convex
sets. Convex functions
have been in the book for longer, as the first
subsection recalls, and every finite support function of
§04 is one too. This section defines the notion, ties it
to convex sets through the epigraph, and proves its
basic theorems: Jensen’s inequality, the convexity of a
supremum of affine functions, which pays a promise of
Chapter 17 §06, a second-derivative test, and
continuity. §11 then spends them on three classical
inequalities.
Throughout, the field is . is a real vector space,
and a set called convex is convex in the sense of Definition 18.1.1. From
the second-derivative test onward we work in , with the standard
inner product and its norm . A function on an interval of is
increasing when implies , as in
Chapter 17 §11, and strictly increasing
when
implies .
Convex
functions and their epigraphs
Look again at three inequalities the book has already
proved. For a norm, (N2) and (N3) of Definition 16.1.1 give for
. For
the top partial sum of a Hermitian
matrix, Chapter 17 §06 derived from Corollary 17.6.5. And
the case of
operator convexity in Definition 17.11.1 (b)
reads for numbers . It is the same
inequality three times, and it deserves a name.
A function is convex when, on every segment of
its domain, its graph lies on or below the
chord.
Definition
18.10.1 (Convex Function)
Let be a
nonempty convex subset of a real vector
space , and let
.
Then is
convex if for all
and all real with . It is
strictly convex if the inequality is
strict whenever and
. It
is concave, or strictly
concave, if is convex, or strictly
convex.
The epigraph of is the subset of the
real vector space , with componentwise operations,
In words: take any two points and of the domain
and any point between them. The left side is
the value of
there. The right side is the value, at the same place,
of the straight line through
and . So the condition says the chord
is never below the graph. Strict convexity forbids the
graph to touch the chord anywhere strictly between two
distinct points. The epigraph is everything on or above
the graph.
The domain must be convex, and this is the
only thing to check. The point
must lie in , or
is not defined
there. That is exactly what Definition 18.1.1
guarantees.
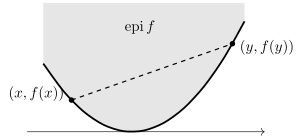
The picture shows on : the dashed chord
lies above the graph between its endpoints, and the
shaded region is the epigraph.
Example
(First convex functions)
Check each against Definition 18.10.1.
- (a) An
affine function , with a linear
functional on (Definition 5.1.1) and
.
- (b) A norm on .
- (c) on , and more generally
on for a symmetric
.
Solution.
(a) Since is linear and
,
Equality holds, so is convex, and so is
: an affine
function is both convex and concave, and neither
strictly. The constant functions are the degenerate case
. They
matter because they show that convexity by itself forces
no growth at all.
(b) By (N3) and
then (N2) of Definition 16.1.1, with
and for , A norm is not strictly convex: on the ray
through a nonzero , is linear in , so the chord
between
and lies
on the graph.
(c) Expanding and
collecting terms, and the right side is strictly positive when
and . So is strictly convex.
The same expansion with symmetric gives and by (P2) of Definition 13.1.1. So
is convex. The
case , , is .
A nonexample by minimal change.
Replace by
on . With , , and , the left
side is
and the right side is , and is false. What fails is the inequality for
this pair, on the negative half-line, where the graph
bends downward. On the convex domain the same
function is convex, as the one-variable test below
shows. So convexity depends on the domain.
Why this definition. The inequality
is nonstrict so that affine functions and norms, the
most important examples, qualify. Requiring it for every
, not
just ,
is what makes Jensen’s inequality below immediate. The
name comes from the epigraph: a function is convex
exactly when the set above its graph is convex.
Proposition
18.10.1 (Convex Function, Convex
Epigraph)
Let be nonempty and convex, and let . Then
is convex if and
only if is a convex subset of .
Idea. A point lies in the
epigraph exactly when . So the chord inequality for and the statement that
segments between points of the epigraph stay in it are
one inequality, read in two directions.
Proof. Let and . The point
lies in , since is convex, and the second step because , , and
. So
.
Let
and . The points
and lie in , so
by convexity so does . By the
definition of the epigraph this says . This proves
the proposition.
The same one-line argument shows that every
sublevel set of a convex is convex: if and
,
then .
Quick check. Every sublevel set of
a convex function is convex. Is the converse true? Is a
function whose sublevel sets are all convex
necessarily convex?
Solution. No. Take . It is
increasing: if then , since vanishes only at
. So if
and
,
then . Each sublevel set is therefore an interval,
which is convex. But is not convex on
, by the
nonexample above.
Warning. A convex function
need not be differentiable. The function is a norm
on , hence
convex, and it has a corner at : its difference
quotients are for and for , so they have no
limit. The same corner appears in linear algebra. The
map on Hermitian matrices is convex,
as the next two subsections prove, and on the diagonal
matrices it equals . The
corner sits at , where the top eigenvalue is repeated.
Jensen’s
inequality
The definition speaks of two points. Induction
extends it to any finite convex combination (Definition 18.1.3), and
that extension is the form in which convexity is most
often used.
Theorem
18.10.2 (Jensen’s Inequality)
Let be nonempty and convex, and let be
convex. Let , and let
with . Then and If is
strictly convex and every , equality
holds only when .
Idea. Split off the last point. The
remaining weights add up to , and after
dividing by they
are the weights of a convex combination of points, to which
induction applies. The whole combination is then , a combination of
two points, which is where the
definition applies.
Proof. We prove both statements by
induction on . For the weight is , both sides equal , and the
equality clause is empty.
Let and
assume both statements for points. If , every other weight is , both sides equal , and the
equality clause does not apply since . Otherwise . The numbers for are nonnegative
with sum , so by
the inductive hypothesis lies in and Now with
, so
this point lies in because is convex, and Definition 18.10.1 gives
where the second step multiplies (1) by . This proves the
inequality.
For the equality clause, let be strictly convex and
every ,
so that and . If equality holds in the theorem, both
inequalities in (2) are equalities. The second is times (1), so (1) is an
equality, and the inductive hypothesis gives ; then equals this
common point. The first is the two-point inequality with
weights strictly between and , so strict convexity
forces . Hence all points are equal, as
claimed.
In the language of §01, the points lie in the convex set , and
Jensen’s inequality says that their convex combinations
stay there. That is Theorem 18.1.3 read
inside the epigraph.
Suprema
of affine functions
Chapter 17 §06 showed that is the largest of the linear
functions , deduced its convexity, and
ended with a promise: “Chapter 18 studies convex
functions in general, and the observation that a
pointwise supremum of linear functions is convex is one
of its basic facts.” Here is that fact, stated for
affine functions, which include the linear ones.
Proposition
18.10.3 (A Supremum of Affine Functions Is
Convex)
Let be nonempty and convex, and let be a
nonempty family of affine functions on . Suppose that for every
the
set is bounded above, and put Then is convex.
Idea. Each meets its own chord
inequality with equality, and each lies below . So at a point between
and , every is at most the chord
of , and therefore
so is their supremum.
Proof. The supremum exists for each
by
completeness, fact (A1) of Chapter 16’s introduction.
Let and . For each , by Example (First convex functions)
(a) and then at and at , where the inequality uses and . So the right
side is an upper bound for the set , and it is therefore at least that
set’s least upper bound, . This proves the
proposition.
The proof never used that the are affine beyond the
fact that each is convex. So the same argument shows
that a pointwise supremum of convex functions is
convex, whenever it is finite. In particular
the maximum of two convex functions is convex. The
minimum need not be: is concave and not
convex.
Instances. Many convex functions of
this chapter are suprema of linear functions, and this
proposition proves their convexity at a stroke.
- ; ; and 𝛜𝛜, the maximum being attained at the
vector of signs of .
- The support function of Definition 18.4.2 is the
supremum over of the linear functions . So it is convex
wherever it is finite, and in particular the dual norm
of Definition 18.4.4 is
convex.
- Every norm is the maximum of over
(Corollary 18.4.9). This
describes the norm; it is not a new proof of its
convexity, since §04 derived the corollary from the
triangle inequality.
- The largest eigenvalue: by Lemma 13.5.2, , and each is linear.
- The Ky Fan sums , the case that
prompted the promise. They are the subject of the next
subsection.
Convex
functions of a Hermitian matrix
Let or
. The
Hermitian matrices over form a
real vector space: if , , and , then . They do not form a complex one, since
.
This is the space on which Chapter 17 §06 called convex, and it is the
setting here. When it is an instance of the chapter’s
convention that a complex space is treated as a real
one.
Corollary
18.10.4 (The Top Eigenvalue Sums Are
Convex)
Let . On the real vector space of Hermitian matrices over
, the function
is convex. In particular
is convex, and is concave.
Idea. Ky Fan’s theorem writes as a maximum of the
functions , each linear on the real space
of Hermitian matrices, so Proposition 18.10.3
applies. For , change the
sign of .
Proof. By Theorem 17.6.2, .
Fix such a . The
matrix
is Hermitian, so its diagonal entries, and hence its
trace, are real. By Theorem 0.9.6 (1),
respects sums and real
multiples. So it is a linear functional on the real
space of Hermitian matrices, and is the maximum of
this family. By Proposition 18.10.3,
is convex, and
gives .
For ,
the eigenvalues of are the negatives of
those of , so
, as in the proof of Corollary 17.6.6. The
map is convex, because it is the
convex
composed with the linear map , and a
convex function composed with a linear map is convex, by
substituting into Definition 18.10.1. So
is the
negative of a convex function, that is, concave.
This is the fact Chapter 17 §06 anticipated, and its
promise is now paid. Chapter 17 reached convexity by a
different path: Corollary 17.6.5 gives
, and positive homogeneity ,
, turns
subadditivity into convexity. Exercise C1 shows that the
two paths are the same, and the warning at the end of
Chapter 17 §06 still stands: a single with , the
difference of two convex functions, is neither
convex nor concave.
What is not proved here. For a
convex on an
interval, is convex on
the Hermitian matrices with spectrum in that interval, a
statement about sums over the spectrum and far weaker
than the operator convexity of Chapter 17 §11. It is
proved in Chapter 21, and nothing in this chapter uses
it.
A
second-derivative test
For a function on an interval, convexity says the
slope never decreases. The mean value theorem turns an
increasing derivative into a chord inequality.
Lemma
18.10.5 (Increasing Derivative Gives
Convexity)
Let be an open interval and let be
differentiable. If is increasing on
, then is convex; if is strictly
increasing, then
is strictly convex. In particular, if is twice differentiable
with on ,
then is convex,
and if on ,
then is strictly
convex.
Idea. Split the chord at the
intermediate point into two sub-chords,
over and
over . By the
mean value theorem, each slope is a value of inside its
interval, so an increasing makes the left
slope at most the right one. A graph whose chord slopes
increase in this way lies below the long chord.
Proof. Let and ; the
cases , , and are equalities.
Exchanging with
and with if necessary, we
may assume . Put , so that , with By the mean value theorem, fact (A6) of
Chapter 16’s introduction, applied on and on , there are and with Since and is increasing,
. Multiplying by ,
Rearranged, this is . If is strictly
increasing, then , and every inequality is
strict.
For the last sentence, let in . Fact (A6) applied to
gives for some . This is
when , and
when . So
is
increasing, or strictly increasing, and the first part
applies.
Derivatives of polynomials, here and below, come from
Chapter 10 §09: a polynomial is a power series with
finitely many nonzero coefficients, so it converges for
every real argument and that section’s fact (A2)
differentiates it term by term, while its fact (A3), the
linearity of differentiation, handles sums and constant
multiples; a partial derivative is such a derivative
with the other variables fixed. For instance, has , which
is strictly increasing (the Quick check after Proposition 18.10.1), so
is strictly
convex on .
Likewise , with
on , is convex there, which is the claim
made after the nonexample.
In several variables the second derivative is the
Hessian of Definition 14.6.2, and
“”
becomes “positive semidefinite”. Chapter 14 §06 read the
Hessian at a single critical point, where its
definiteness decides a local extremum (Theorem 14.6.4). Here the
Hessian is asked to be positive semidefinite at
every point, and what it decides is
global. Restricting to lines would need a
chain rule the book has not imported, so the proof below
uses only Chapter 14 §06’s (A1), that is
symmetric, and its (A2), Taylor’s theorem with a
remainder satisfying
. It works with second
differences, which (A2) controls directly.
Theorem
18.10.6 (Convexity from the Hessian)
Let be a nonempty open convex set, and let
be twice continuously differentiable.
- (a) is convex on if and only if
for every .
- (b) If
for every , then
is strictly convex on .
Idea. Taylor’s theorem at , applied at
and at and
added, kills the gradient term: For , convexity
makes the left side , so the limit is too. For the other
direction, restrict to a segment and
subtract the chord. If the difference were positive
somewhere, it would have an interior maximum, and at a
maximum every second difference is . That contradicts a
strictly positive limit. So the
argument handles first, and reaches by adding
and letting .
Proof. Write . For , , and
real small
enough that , put
Step 1: the second difference. We
claim as . If both
sides are .
Otherwise Chapter 14 §06’s (A2) at , with and
with , gives Adding the two and subtracting , and the bracket tends to because . The same expansion shows that is continuous: , and each term
tends to as .
Step 2: (a), .
Let be convex,
, and
.
For small ,
,
so , that is, . Dividing by and letting , Step 1 gives
, since a nonstrict inequality survives a
limit. The matrix is symmetric
by Chapter 14 §06’s (A1), so
by Definition 13.1.1.
Step 3: a maximum principle. Let
in , put , and let be
continuous with the following property: for every point
with , the limit exists and is
strictly positive. We claim Define on . Every point of
the segment lies in , since is convex. So is continuous, and
.
The subtracted part is affine in , so its second
differences vanish, and with .
Suppose for some . The interval is closed and
bounded, hence compact by fact (A3) of Chapter 16’s
introduction, so by the extreme value theorem, fact
(A4), attains a
maximum value at
some point. Then . If the maximum is attained only
at or , then , so
attains it too.
Either way, for some . For
, both , so the second difference of at is , and so is its
limit . This contradicts . Hence on , which is the
claim.
Step 4: (b). Let for
every . By Step 1, has
whenever , and it is continuous. So Step 3 gives
for all
in and . Renaming
as , this is strict
convexity.
Step 5: (a), .
Let for every . Let in
, , , and . Put
, which is
continuous. Expanding the norms, so by Step 1 the limit for is . Step 3
applies. With , it gives Let through . The
inequality survives as a nonstrict one, and gives . The cases ,
, and are equalities. So
is convex. This
proves the theorem.
For , part
(a) says that a twice continuously differentiable on an open interval is
convex exactly when , and
its “if” half is Lemma 18.10.5 again.
Quick check. The function is strictly
convex on . Is
its Hessian, the matrix ,
positive definite at every point? What does this say
about part (b)?
Solution. No.
vanishes at ,
so the
matrix is
positive semidefinite but not positive definite. Yet
is strictly
convex, as shown after Lemma 18.10.5. So the
converse of part (b) fails: strict convexity does not
force a positive definite Hessian.
Convexity is tested segment by segment, so is convex exactly when
its restriction to every line is
convex. The phrase every line matters.
Warning. Convex along every
line through one point is not enough. Let on . On each line
through the origin, , a nonnegative multiple of the
convex , so each
such restriction is convex. But is not convex. On the
segment from
to , a line
that misses the origin, is at both ends and at the
midpoint. So the value at the midpoint exceeds the
average of the
end values.
The Hessian test sees the same failure without
guessing the segment. Here so at the determinant is . The two
eigenvalues of this symmetric matrix have product , so one is negative,
and . Part (a) confirms that is not convex.
Continuity
The warning about shows that convexity does not buy
differentiability. It does buy continuity on an open
set, and in finite dimension the proof is short: a bound
from above near a point is enough, and Jensen’s
inequality supplies one.
Theorem
18.10.7 (Convex Functions Are
Continuous)
Let be a nonempty open convex set and let
be convex. Then
is continuous on .
More precisely, for every there are
and
with
Idea. ① Bound above on a small ball
around .
The ball sits inside the “diamond” spanned by the points , and Jensen bounds on the diamond by its
largest value at those points. ② Turn an upper bound
into a two-sided linear bound. Walk from toward and
on to the edge of the ball: convexity makes the rise
over the short step at most a fraction of the rise over
the whole way. Then walk the other way for the lower
bound.
Proof. Fix . Since
is open, Proposition 18.1.6 (a)
gives such
that every point within distance of lies in . Put . The points and lie in , so let be the largest value of
at them.
Step 1: an upper bound. Let with , and let if and otherwise,
so that . Then a convex combination: the weights are
nonnegative and add up to . By Theorem 18.10.2, . Put . If , then by Proposition 16.1.2, so .
Step 2: the linear bound. Put , which is because is one of the
points defining .
Let ; for there
is nothing to prove. Put and , so
that and .
First, so convexity gives ,
that is, using Step 1 at . Second, as one checks by multiplying out and using
. Here lies
in , and convexity
gives , that is, using Step 1 at . Together,
.
Step 3: continuity. If ,
then for all large , and for those Step 2 gives . So is
continuous at , in the
sequential sense of Chapter 16’s introduction. As was arbitrary,
this proves the theorem.
By Theorem 16.2.2 the choice of
the Euclidean norm is immaterial: every norm on gives the same
continuous functions. Both hypotheses of the theorem are
needed.
Warning. The domain must be
open. On the closed interval , let on and . It is convex:
the right side is never negative, and the left side
is unless , which
for
forces ,
where both sides equal . But . A convex function can jump at a boundary
point of its domain.
The basic theory is now in place. A convex function
is one with a convex epigraph; Jensen’s inequality
extends its defining inequality to every finite average;
every supremum of affine functions is one, which
accounts for the Ky Fan sums; the Hessian tests for it;
and on an open set it is continuous. What it has not yet
done is prove an inequality the book did not already
know. §11 does that: with a logarithm constructed from
the exponential, Jensen’s inequality for gives the weighted
arithmetic–geometric mean inequality, and from it come
Young’s and Hölder’s inequalities, the triangle
inequality for every -norm, and the dual
norms that §04 left open.
Exercises
A. Check your
understanding
Exercise
(A1)
- (a) Define “ is convex on ”, and explain why is required to be
convex.
- (b) Decide whether
the following is correct, and justify your answer: if
and are convex on , then so are and .
- (c) Decide whether
the following is correct, and justify your answer: if
and are convex on , then so is their
product .
- (d) Decide whether
the following is correct, and justify your answer: a
convex function on is
differentiable.
- (e) Decide whether
the following is correct, and justify your answer: if
is convex along every line through the
origin, then is
convex.
- (f) Name the facts
of analysis that the proof of Theorem 18.10.6
uses.
Solution.
(a) Let be a nonempty convex
subset of a real vector space. Then is
convex if for all
and all (Definition 18.10.1). The
left side evaluates at , and this point is in the domain
for every choice exactly when is convex.
(b) Correct.
Adding the inequalities for and for gives the inequality
for . For the
maximum, the remark after Proposition 18.10.3
applies: its proof works for any family of convex
functions, and here the family is .
(c) Incorrect.
is affine
and is
convex (Example (First convex functions)),
but is not
convex on : at
, , and their midpoint
the nonexample
after Example (First convex functions)
gives .
(d) Incorrect.
is
convex and not differentiable at , as the first warning
of the section shows.
(e) Incorrect.
is
convex along every line through the origin but not
convex, since .
(f) Chapter 14
§06’s assumptions (A1), the symmetry of the Hessian, and
(A2), Taylor’s theorem with a second-order remainder;
facts (A3) and (A4) of Chapter 16’s introduction,
compactness of and the extreme value theorem, in the
maximum principle; and the algebra of limits, in the
form “a nonstrict inequality survives a limit”.
B. Practice
Exercise
(B1: Which are convex?)
Determine which of the following functions are convex
on the given domain. Justify your answer.
- (a) on .
- (b)
on .
- (c) on .
- (d) on .
- (e) on .
Solution.
(a) Convex,
indeed strictly convex. is a polynomial, so
twice continuously differentiable, with constant Hessian
,
which is symmetric. For ,
which is positive unless and , that is,
unless . So at every point, and Theorem 18.10.6 (b)
applies.
(b) Not convex.
Take and , with midpoint . Then , while . The inequality of Definition 18.10.1 fails
with .
(c) Convex. The
three functions , , and
the constant are
affine, and is
their maximum, so Proposition 18.10.3
applies.
(d) Strictly
convex. For and small , so . If then , so : is strictly
increasing on , and Lemma 18.10.5 gives
strict convexity.
(e) The question
has no answer: Definition 18.10.1
requires a convex domain, and this one is not. It
contains and
but not their
midpoint , so the
defining inequality is undefined for , , .
C. Going deeper
Exercise
(C1: Subadditive and homogeneous)
Let be positively homogeneous:
for every and every
real .
- (a) Prove that is convex if and only
if for all .
- (b) Deduce that
every norm on
is convex, and that Corollary 17.6.5 and
Corollary 18.10.4 are
equivalent statements about .
Solution.
(a) Let be convex. By
homogeneity with and then convexity with , Let be subadditive, and let
. By
subadditivity and then homogeneity with the nonnegative
numbers and ,
(b) A norm is
positively homogeneous by (N2) of Definition 16.1.1, since
for , and
subadditive by (N3); so it is convex by (a). This is a
second proof of Example (First convex functions)
(b). The function is positively
homogeneous on the Hermitian matrices, since multiplying
by
multiplies each eigenvalue by and keeps their order.
So by (a), subadditivity of , which is Corollary 17.6.5,
holds exactly when is convex, which is
Corollary 18.10.4.
Exercise
(C2: Tangent lines)
Let be an open interval and let be
differentiable and convex.
- (a) Prove that for all .
- (b) Deduce that
for every
: a
differentiable convex function is the maximum of its
tangent lines.
Hint: in (a), apply the definition to the points
and with weight on , and let .
Solution.
(a) If both sides are
equal. Let
and .
Convexity with weight on gives , that is, The fraction is a difference quotient of at with step . Take
; the step
tends to , so the
fraction tends to . A nonstrict
inequality survives the limit, so , as claimed.
(b) For fixed
, each is at most by (a), and . So the
maximum over
exists, is attained at , and equals . Each is an affine
function of , so
this is the converse of Proposition 18.10.3, for
differentiable functions.
Exercise
(C3: Where a convex function is largest)
- (a) Let be
convex, and let
be the convex hull . Prove that .
- (b) Let
and let be the
triangle . Find the maximum and the
minimum of on
, and say where
each is attained.
Solution.
(a) Each lies in , so the maximum over
, if it exists, is
at least .
Conversely, let . By Theorem 18.1.3, for some weights with sum , and Theorem 18.10.2 gives
.
So is an
upper bound for
on that is
attained, hence the maximum. Compare Corollary 18.8.6, which
says the same for a linear function on any compact
convex set, with extreme points in place of the .
(b) The Hessian
is the constant symmetric matrix , and , so it is
positive semidefinite and is convex by Theorem 18.10.6 (a). By
(a) the maximum is the largest vertex value: , , and . So the maximum is , attained at all three
vertices. For the minimum, , with equality only at
. And lies in . So the minimum is
, attained only at
the interior point . The maximum of a convex function sits at
vertices; its minimum need not.