Chapter 13 used the number
as a test: positive for every nonzero means positive
definite, nonnegative means positive semidefinite, and
that was the end of it. Chapter 13 §05 then noticed that
the test carries more information than the verdict —
normalized, it ranges over the interval between the
smallest and largest eigenvalues — and stopped there.
This section makes the normalized quantity an object
with a name, finds its range exactly, finds the vectors
where it is flat, and extracts a first description of
every eigenvalue as a maximum. The description is
correct and unsatisfying, and saying precisely why is
the business of §02.
Throughout, is or , every matrix is
Hermitian, and its eigenvalues are indexed
decreasingly, , repeated according to
multiplicity. The indexing presupposes that the
eigenvalues are real, which is Theorem 12.2.1.
Inner products are the standard ones of , linear in the first
slot.
From a
test to an object
Look at what Lemma 13.5.2 actually
says. For a unit vector , the number
lies between and , and it
reaches both ends. The restriction to unit vectors is a
nuisance: doubling quadruples ,
so for
the raw quantity has no bounded range at all and every
statement about it must carry the clause “for ”
along. Dividing by removes
the nuisance permanently, and the resulting expression
occurs often enough in what follows to deserve a name of
its own.
The Rayleigh quotient measures how much a
Hermitian matrix stretches a vector along its own
direction, on a scale where the vector’s length has been
divided out.
Definition
17.1.1 (Rayleigh Quotient)
Let be or and let be
Hermitian. The Rayleigh
quotient of is the function defined at every with
, and at no other vector.
For a self-adjoint operator on a finite-dimensional
inner product space over , the same formula ,
for , defines the Rayleigh quotient of
.
Clause by clause. The word Hermitian
is what makes the values real, and so what makes it
sensible to ask for a maximum: by Proposition 11.6.7
(a), for every , even over . The condition
is what makes the fraction
mean anything: exactly for , by
positive definiteness of the inner product (Definition 11.1.1),
and there is no value to assign at — the numerator
vanishes there too, and the quotient would have to be
given a value by hand, which no theorem below would
thank us for. So is a real-valued
function on .
Well-definedness has a second half, and it is
the useful one. For a scalar , so the factor cancels
and The Rayleigh quotient is therefore constant on
each line through the origin with the origin removed. It
is really a function on the set of lines, and the
cheapest way to evaluate it is to normalize: for a
unit vector , Every statement below may be read either way —
over all nonzero vectors, or over the unit sphere — and
we shall move between the two without comment.
Example
(A diagonal matrix, and the whole chapter in
miniature)
Let with real . Compute .
Solution. For we have , so The weights are nonnegative and
sum to . So is a
weighted average of the diagonal
entries, and is nothing but
the recipe for the weights.
That one line is the entire chapter in miniature, and
it is worth pausing on. A weighted average of can be
any number between the smallest and the largest, and
nothing else; it equals the largest only when all the
weight sits on the largest entries; and to force it down
to the second largest one must forbid
the weight from sitting on the first. Every theorem in
this chapter is one of those three sentences, stated for
a general Hermitian matrix, where the diagonal entries
are replaced by the eigenvalues and the coordinates
by the
coefficients of in an
orthonormal eigenbasis. The spectral theorem is what
turns the general case into this one.
Example
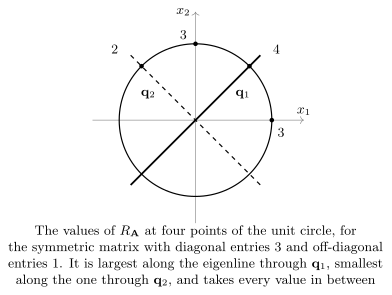
(A symmetric matrix on the unit circle)
Let . Describe on the unit
circle, and find its largest and smallest values.
Solution. The eigenvalues are and , with orthogonal
eigenvectors and : indeed and .
Writing a unit vector as , So the values run over ; the maximum occurs at and , that is
along the line through , and the
minimum at and , along the line
through .
At and
the
value is , the
average of the two eigenvalues, which is also .
Example
(Two matrices whose quotient is forced)
Two further cases, at opposite extremes.
- (a) The
identity. for every .
The quotient is constant, and the constant is the only
eigenvalue. More generally for real
.
- (b) An
orthogonal projection. Let be the
matrix of the orthogonal projection onto a subspace
, so and (Theorem 13.13.1). Then
, so the fraction of that survives
the projection. Since by Theorem 11.1.3, it
equals exactly
when , that is on ,
and exactly when
, that is on
— matching the eigenvalues and of .
Case (a) is the degenerate one, and it earns its
place: when all the eigenvalues coincide the interval of
values collapses to a point, every nonzero vector is an
eigenvector, and every theorem below becomes an equality
between two copies of the same number. A statement that
fails to survive has been stated wrongly.
Example
(Change one word: drop Hermitian)
Take , which is not Hermitian, and form
anyway. At the numerator is and the denominator is , so the quotient is
, which is not
real. The clause that fails is the word
Hermitian in Definition 17.1.1, and
it fails at the first step: Proposition 11.6.7
(a) is what made the numerator real, and its hypothesis
is gone.
Over the
failure is quieter and worse. For and real
, so the quotient is real, and identically . It is perfectly well
behaved and tells us nothing: has no real eigenvalue
at all, and there is no interval
for the quotient to describe.
Why this definition, then. Dropping “Hermitian” costs
the reality of the values, hence any notion of largest;
the real
example above shows that it also destroys the link with
the spectrum even when the values happen to stay real.
Dropping the denominator costs scale invariance, and
with it the possibility of writing without a side
condition. Keeping the denominator but allowing costs
nothing but sense.
Warning. and
are the same number only for unit . The
bound of Lemma 13.5.2 is stated
for unit vectors and is false without that hypothesis:
for and
it would read . The bound , by contrast, holds for every
. Whenever a maximum over “all ” appears below,
it is a maximum of the quotient; the
un-normalized form of the same statement always carries
with it.
What
values it takes
Lemma 13.5.2 gives the
two ends of the range. The following proposition adds
that nothing in between is missing, which is a smaller
statement than it looks and is worth proving explicitly
rather than quoting a continuity argument.
Proposition
17.1.1 (The Range of the Rayleigh
Quotient)
Let be Hermitian, . Then the whole closed interval. In particular and both are attained, at unit eigenvectors
for
and .
Idea. Two inclusions of quite
different weights. is Lemma 13.5.2 with the
normalization divided out, and costs one line. asks for a
vector realizing each intermediate value; the natural
instinct is to move continuously along the sphere from a
top eigenvector to a bottom one and quote the
intermediate value theorem, but there is no need to
import anything. Mixing a top eigenvector and a bottom
eigenvector in the proportion puts weight on and on , and the
weighted average of Example (A diagonal matrix, and the whole chapter in miniature)
sweeps the interval as does.
Proof. By the spectral theorem for
matrices — Corollary 12.4.3
over , Corollary 12.5.2
over — there is
an orthonormal basis of with for every .
Let
and put , a unit vector. By the
scale invariance established above, , which lies in
by Lemma 13.5.2.
Let
. If the interval is the single point
, and we are done. Otherwise
put which is legitimate because the denominator is
nonzero and both square roots are of nonnegative reals.
Note here,
since , so and are distinct
members of an orthonormal list. By Theorem 11.2.1 (c),
so in particular .
Since , Theorem 11.2.1 (b)
gives the last equality by the choice of . So every point of the
interval is a value.
For the attainment, and . This proves the proposition.
So the range is an interval, not a
finite set, even though has at most eigenvalues. That
single fact is responsible for most of the confusion
this chapter has to clear up, and the warning below
spells out why.
Quick check. For ,
write down two unit vectors with Rayleigh quotient , each having one zero
coordinate, in different positions.
Solution. Mixing and as in the
proof: gives and , for
which . Mixing
and
instead:
gives and
, for
which . A value of
is realized
by many vectors, and they need not resemble each
other.
Where the
quotient is flat
The maximum and the minimum are attained at
eigenvectors. There is a converse, and it identifies the
eigenvectors among all vectors by a condition that does
not mention eigenvalues: they are the places where does not move to
first order. Everything needed is one algebraic
identity, exact for every , so no calculus
enters.
Proposition
17.1.2 (Critical Points of the Rayleigh
Quotient)
Let be Hermitian, let be a
unit vector, and put . For every and
every
with ,
(17.1.1)
Moreover:
- (a) for every
if and only if ;
that is, if and only if is an
eigenvector of ,
necessarily for the eigenvalue .
- (b) If for every ,
then the condition in (a) holds. The same is true if
for every .
Idea. Expand the numerator and the
denominator of in powers of and subtract times the denominator
from the numerator. The constant terms cancel by the
definition of ,
and what is left is exactly Eq. 17.1.1. The
coefficient of is
the object of interest: (a) says it vanishes in every
direction precisely at eigenvectors, and (b) says that
at a maximum it must vanish, since otherwise a small
step in the right direction would increase the quotient
— the term
cannot interfere, because for small it is smaller than the
term.
Proof. The identity.
Expanding by sesquilinearity, where the second line used , the first
equality because
is Hermitian and the second by conjugate symmetry (Definition 11.1.1),
together with for the unit vector . The same
computation with
replaced by ,
where the constant term is ,
gives Since
is real, .
Subtracting
from the first display therefore leaves and dividing by gives Eq. 17.1.1.
(a) Put . If
then and every
vanishes. Take : the
hypothesis gives , so by
positive definiteness, that is .
Since , this exhibits as an
eigenvector for the eigenvalue .
(b) Suppose maximizes and, for a
contradiction, that for some ; then .
Put , and let be any real number with
which is possible because the two upper bounds
are positive. The first bound gives , by the triangle inequality (Corollary 11.1.6),
so and the identity applies. The second
gives , so has the same sign
as , and hence
.
By Eq. 17.1.1, contradicting the maximality of . So
for every
. For a
minimizer, apply what has just been proved to , whose Rayleigh
quotient is , so that a
minimizer of
is a maximizer of ; the condition in
(a) for and
is the same
condition. This proves the proposition.
Call a unit vector a
critical point of when the condition
in (a) holds, that is, when the coefficient of in Eq. 17.1.1 vanishes in
every direction — when moves away from
only at second order. Parts (a) and (b) then say:
the critical points of on the unit sphere
are exactly the unit eigenvectors of , the critical values
are exactly the eigenvalues, and every maximizer and
every minimizer is among them. That the eigenvalues
are all realized as critical values is a direct
computation: , and each is a unit
eigenvector, hence a critical point by (b).
Why the
second eigenvalue is not a second maximum
Warning. is not “the
second largest value of ”, and there is no
sense in which it could be. Take , so
,
,
. By
Proposition 17.1.1 the
set of values of is the whole
interval .
Three things go wrong at once.
- There is no second largest value.
The values below
form the interval , which has no largest element. So the phrase
does not describe a number.
- The value is attained,
but so is every other value, and not only at
eigenvectors. At the quotient is , and is not an
eigenvector of :
it mixes the eigenvectors and of the first
and the third eigenvalues, and plays no part
in it.
- Removing a direction does not help by
itself. At , which is orthogonal
to the eigenvector of , the quotient
is , strictly between and . Constraining
to a
subspace changes the answer, and which subspace is
everything.
Whatever describes must be a
maximum over something smaller than the sphere.
The last bullet says what to try. Cutting the sphere
down by orthogonality to the top eigenvector does work,
and the proof is Example (A diagonal matrix, and the whole chapter in miniature)
again, with the top entry removed from the average.
Proposition
17.1.3 (Eigenvalues by Deflation)
Let be Hermitian and let be an orthonormal basis of with for every . Then for every with , the maximum being attained at .
For the list
of constraints is empty and the statement is Proposition 17.1.1.
Proof. Let . By Theorem 11.2.1 (a)
every satisfies ,
so
exactly when .
Let with , and write , so that . Then , and Theorem 11.2.1 (b),
(c) give Hence is a
weighted average of with nonnegative weights summing to . The largest of those
eigenvalues is , because
the list is indexed decreasingly, so .
Finally , since the are
orthonormal, and . So the bound is attained and the
supremum is a maximum. This proves the proposition.
Quick check. In Proposition 17.1.3,
does the value of the maximum depend on which
orthonormal eigenbasis is chosen? Does the maximizing
vector?
Solution. The value does not: it is
, a
number attached to alone. The maximizing
vector generally does, and so does the constraint set
. For and
, one
admissible eigenbasis is , giving and maximizer ; another is
,
giving a different and the maximizer .
Both maxima equal .
What is
still wrong
Proposition 17.1.3 is
a complete answer to the question “what is , as an
optimization?” and it is nearly useless. The reason is
visible in its statement: the constraint set is built
from , which are eigenvectors of . To use the formula
one must already know the eigenvectors, and to know the
eigenvectors one must already have solved the problem
the formula claims to describe. It is a description of
in
terms of ’s own
answer.
The cost is not merely aesthetic. The whole point of
turning an eigenvalue into an optimization is to compare
the eigenvalues of different matrices:
to say that forces , or that perturbing moves only a little.
A comparison needs the two optimizations to run over the
same set. Deflation gives as a
maximum over the orthogonal complement of ’s top eigenvectors,
and
as a maximum over the orthogonal complement of ’s top eigenvectors,
and those two subspaces have nothing to do with each
other. Nothing can be concluded.
Chapter 13 §13 promised that “Chapter 17
characterizes the eigenvalues of a Hermitian matrix as
maxima and minima of
— at which point the test becomes the theory”. Proposition 17.1.1 and
Proposition 17.1.3 are
the first installment of that, and they show that the
promise can be kept. The test has already become a
statement about a single number: exactly when
is
positive, and exactly when it is nonnegative, which is the
eigenvalue criterion of Theorem 13.1.5 and Theorem 13.1.4 read
through Proposition 17.1.1.
The rest of it is the removal of the eigenvectors from
the statement, which §02 achieves by a device that looks
extravagant and is exactly right: keep the maximum over
a subspace, but let the subspace vary over
all subspaces of the appropriate
dimension, and take the minimum of what comes out.
Exercises
A. Check your
understanding
Exercise
(A1)
- (a) State Definition 17.1.1,
naming both hypotheses, and say what each one is
for.
- (b) Prove that for every scalar , and explain why
this makes a
function on lines.
- (c) Determine
whether the following is correct, and justify your
answer: if is symmetric with three distinct
eigenvalues, then takes exactly
three values.
- (d) State Proposition 17.1.3,
and say in one sentence why it is not a satisfactory
description of .
- (e) Give a Hermitian
and a vector
that is
not an eigenvector of but has equal to
an eigenvalue of .
Solution.
(a) Let be or and Hermitian.
For , the Rayleigh quotient is .
Hermitian makes the numerator real (Proposition 11.6.7
(a)) and ties the values to the spectrum;
makes the denominator nonzero (Definition 11.1.1).
(b) and
likewise ; the
factor cancels. So is constant on
, the punctured line through , and its value
depends only on which line lies
on.
(c) Incorrect. By
Proposition 17.1.1 the
set of values is the whole of the interval , which is infinite whenever
, and distinct eigenvalues
guarantee that.
(d) With an orthonormal eigenbasis ordered
so that , is the
maximum of
over the nonzero vectors orthogonal to . It is unsatisfactory because
the constraint set is built from eigenvectors of , so the formula
presupposes the answer and cannot compare two different
matrices.
(e) and
: , while
is not a multiple of . (Any mixture of
a top and a bottom eigenvector in the right proportion
does the same job.)
B. Practice
Exercise
(B1: Locating four values)
Let Its eigenvalues are , with
eigenvectors , , and respectively;
you may take this as given. Compute for
, , , and
, and check each value against Proposition 17.1.1.
Hence exhibit a noneigenvector at which equals an
eigenvalue.
Solution. The three given vectors
are pairwise orthogonal, each of norm , so , , is an orthonormal eigenbasis
with ,
,
. By
Proposition 17.1.1
every value must lie in .
For : ,
so and ,
giving . (This is the diagonal entry , as it must be for
a standard basis vector.)
For : and , while ; so
.
For : and , ; so
.
For :
and , ; so
.
All four values lie in . The last one
equals , yet is not a multiple of , so is not an
eigenvector. This is the trap of the warning above, in a
concrete matrix.
Exercise
(B2: A prescribed value)
With and the
orthonormal eigenbasis of Exercise (B1: Locating four values),
use the construction in the proof of Proposition 17.1.1 to
produce a unit vector with .
Then find, by mixing and in equal
proportion, a vector with integer entries whose Rayleigh
quotient is .
Solution. For the first, with and gives , so
a unit vector with .
For the second, , whose Rayleigh
quotient is the average — matching the direct computation in Exercise (B1: Locating four values).
Equal proportions of two orthonormal eigenvectors give
the plain average of their eigenvalues.
Exercise
(B3: The quotient of a projection)
Let and let be the matrix of the
orthogonal projection onto .
- (a) Compute , and list the
eigenvalues of
with multiplicity.
- (b) Compute for
, , and
, and check each against Proposition 17.1.1.
Solution.
(a) The two
spanning vectors are orthogonal, of norms and , so and form
an orthonormal basis of and , that is Its eigenvalues are with multiplicity (on ) and with multiplicity (on ), so
and .
(b) By Example (Two matrices whose quotient is forced)
(b), . For
: , so and . For :
, so . For
: , so
and ,
giving . All three lie in , and the middle one attains the lower
end, as it must, being a nonzero vector of .
C. Going deeper
Exercise
(C1: Why the quotient estimates eigenvalues so
well)
Let be Hermitian with orthonormal eigenbasis
, .
- (a) Prove that for
every unit vector ,
- (b) Deduce that if
then
approximates with error
at most : an error in the
eigenvector of size costs only
in
the eigenvalue.
- (c) Show that the
exponent cannot
be improved, by computing both sides for and .
Hint for (a): expand in the
eigenbasis and compare the two sums term by
term.
Solution.
(a) Write , so by Theorem 11.2.1 (c).
As in Proposition 17.1.3,
, so where the term was dropped because it is and each remaining
factor was enlarged to ,
legitimate since and the eigenvalues decrease.
On the other side, again by Theorem 11.2.1 (c),
Combining the two displays gives the
inequality.
(b) Immediate
from (a), since the right-hand side is increasing in
.
(c) Here , , and .
The vector is a unit
vector with while . The bound in (a) reads , which is true, and the ratio
of the two sides is which tends to as . So the
error really is of order , not
smaller, and the constant in (a) is sharp in the limit.
This second-order accuracy is why the Rayleigh quotient
is the standard way to read an eigenvalue off an
approximate eigenvector, and Chapter 24 builds an
iteration on it.
Exercise
(C2: The equality case at the top)
Let be Hermitian and let be the eigenspace of the
largest eigenvalue.
- (a) Prove that if
and , then .
- (b) Deduce that
.
- (c) Show that the
corresponding statement for an intermediate eigenvalue
is false, by naming a matrix, an index
with , and a
vector.
Solution.
(a) We may assume
, by scale invariance and because is a
subspace. Write for an orthonormal
eigenbasis as above, so and . Then
a sum of nonnegative terms. Every term is
therefore , so
whenever
. Hence , a combination of
eigenvectors for , so .
(b) is (a),
together with . If then , so .
(c) Take , , and . Then
, but is
not a multiple of , so . The argument in (a)
breaks because the terms are no longer all of the same sign:
the term is
negative and cancels against the term instead of
forcing both to vanish.
Exercise
(C3: What the quotient cannot see)
Let be an arbitrary matrix, not assumed
Hermitian, and put so that with and .
- (a) Prove that for every .
- (b) Deduce that over
, the function
determines and nothing whatever
about . Give two
distinct real matrices with
the same such function.
- (c) Over , determine whether
for all forces . Justify your
answer.
Solution.
(a) By conjugate
symmetry and the definition of the adjoint, . Hence
(b) Over every inner product
value is real, so (a) reads for all : the function
sees only . It
determines
completely, since two symmetric matrices with the same
quadratic form are equal (Theorem 12.2.5
applied to their difference). It sees nothing of : for both functions are identically , since , yet . This is Exercise (C3: What the real quadratic form does determine)
in matrix language.
(c) Yes, over
it does force
. This is Theorem 12.2.6,
and the reason the complex theory is the cleaner one: a
complex quadratic form determines its matrix, so nothing
is invisible. Concretely, (a) gives , and applying the
hypothesis to —
or expanding and
— kills as well.
The real
matrix of (b)
shows that the same statement over is false, so this is
genuinely a fact about the field.